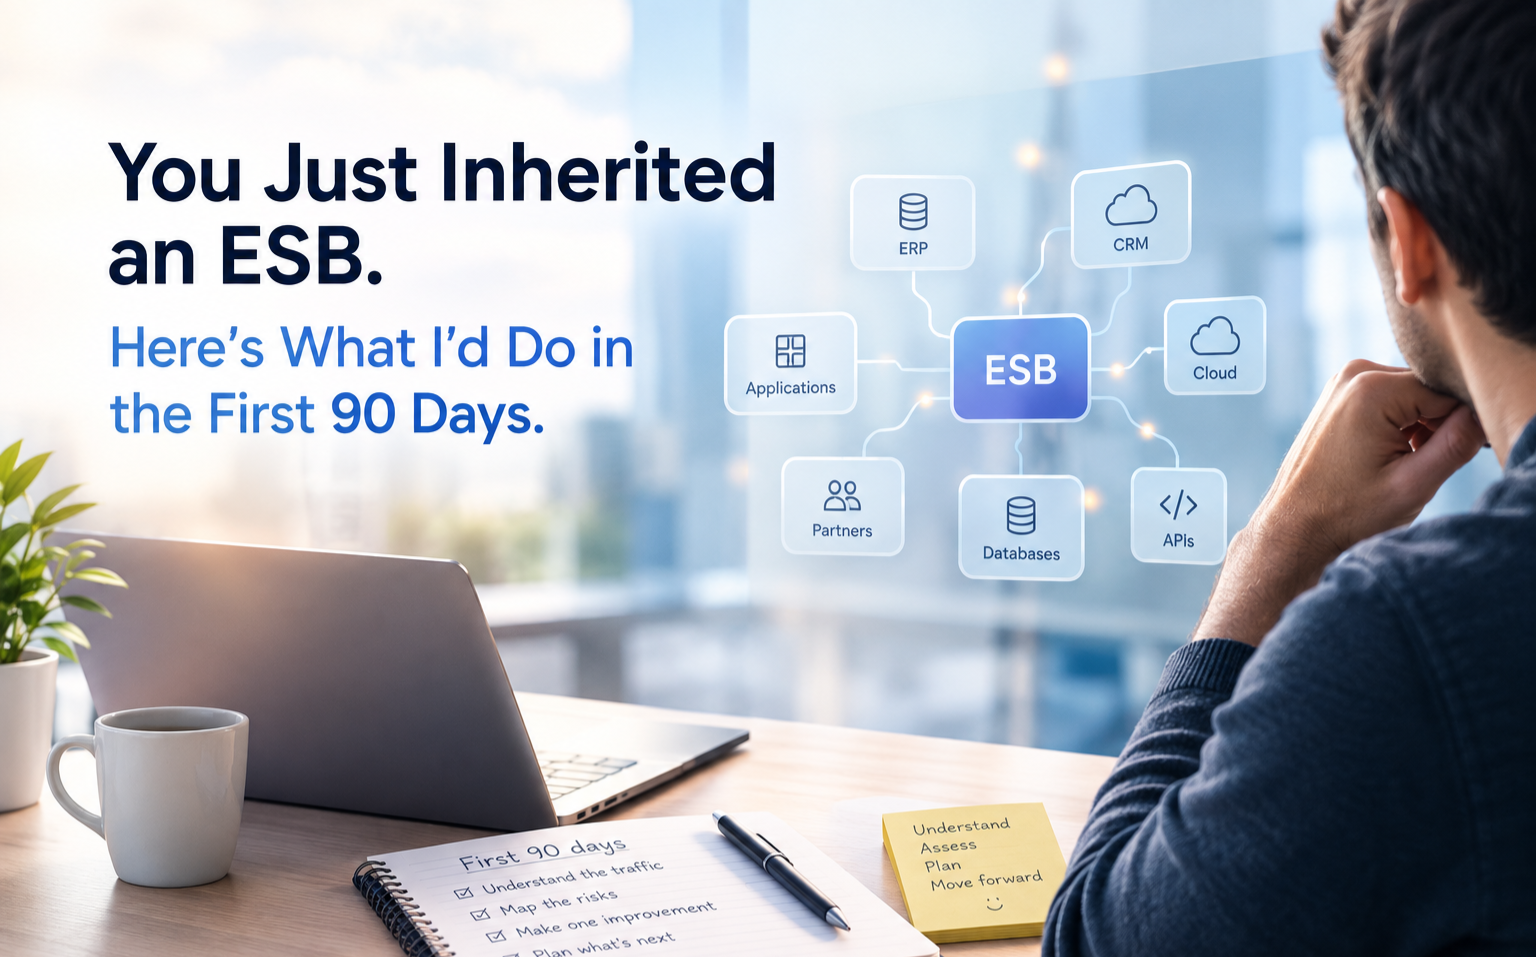
If you’ve just inherited an ESB, don’t feel like you have to improve it on day one. For the first ninety days, your job is to understand what’s really there, what actually carries traffic, and what is most likely to break. Weeks 1–4: change as little as possible and build two maps. Weeks 5–8: turn what you’ve learned into a short, practical risk register. Weeks 9–12: make one useful operational improvement, then write the plan. The three things I’d resist early on are rewriting something too soon, picking a replacement platform before you understand the estate, and promising a migration date. They all look decisive, but they can create problems before you have the information to make a good call.
The job description probably says something like: responsible for the design, development, deployment and support of the Enterprise Service Bus and infrastructure layer. Sounds straightforward. Then you get access and discover that you’re now responsible for a mission-critical system that has been growing for years.
What that usually means in practice is years of integration built by different people, with plenty of them no longer around. The documentation may be useful, but it probably won’t tell you the whole story. The estate works. The tricky part is figuring out exactly why.
So I’d make the first ninety days about getting three answers you can stand behind: what is here, what actually matters, and what is most likely to break. Nearly every bigger decision you make later will depend on those answers. It’s better to wait for the right information than to make a fast decision based on a bad assumption.
01 / Weeks 1–4
Change as little as possible. Build two maps.
There will probably be pressure to show results quickly. That’s normal, but don’t let it push you into changing things you don’t understand yet. One of the most useful things you can produce in month one is two simple documents that the organisation probably doesn’t have today.
The traffic map
List every flow and how many messages it actually handled over the last ninety days. Don’t just copy the artifact list from the admin console. You want to know what is really being used. Sort it by traffic so the busy flows rise to the top.
Two numbers will tell you a lot: how many flows are actually carrying traffic, and how many are sitting there doing nothing. In an inherited estate, the second number is often much bigger than people expect. That gives you a very different picture from simply counting artifacts.
The consequence map
For each live flow, find out who notices when it stops, how quickly they notice, and what they do next. This isn’t something you can get from the platform. You have to ask the people who depend on the flow.
This is also where you become useful very quickly. When something breaks, everyone wants to know what matters, who needs to know, and what happens next. If you already have that information, you’re ahead of the problem.
If you sort the estate by artifact count, you get a list of things. If you sort it by business consequence, you start getting a plan. The difference is mostly a few weeks of talking to people outside the integration team.
Why the consequence map is worth doing early
While you’re building the maps, do one very non-technical thing in week one: find out who gets called when integration breaks and go talk to them. It might be an operations lead, someone in finance who watches for a file, or an account manager who deals with partners. These people often know how the estate behaves in the real world better than the documentation does.
02 / Weeks 5–8
The risk register: what is likely to wake you up
Once you have the maps, month two is about turning them into a short list of things that could genuinely hurt you. Not a twenty-page generic risk assessment. I’d aim for three to five risks that are realistic enough to wake you up at 2am, with a practical answer for each.
These five areas are a good place to start. Work through them in roughly this order, because some risks can make every other problem much harder to deal with:
The single point of knowledge
Find the person who knows the orchestrations, or the contractor who understands the partner setup. Then find out whether they’re still available. This is the risk that can turn an ordinary incident into a crisis. The good news is that the fix is mostly in your hands: talk to that person, go flow by flow, and write down what you learn.
The undocumented tolerance
There is probably a flow somewhere that accepts bad input because a partner has been sending it that way for years. You’re more likely to find these cases in suspended-message history and old tickets than in the schemas. Keep track of them. They can become painful surprises during a rebuild or migration.
The dependency floor
Find out exactly what the platform depends on: operating system, database, runtime, and their support dates. On older estates, the database underneath the integration platform can reach end of support before the platform itself. That can quietly become your real deadline. Check it now rather than discovering it during a migration project.
No rehearsed recovery
Don’t just ask whether a recovery procedure exists. Ask when someone last tested it. A rollback procedure that has never been used is still an assumption. If you can safely rehearse recovery on one non-critical flow, that’s a small exercise that can tell you a lot.
The certificate, credential or licence with a deadline
Check partner certificates, service-account passwords and rotation policies, platform licences, and support contracts. None of this is exciting, but it is easy to overlook and easy to prevent. Put the important dates on one expiry calendar before they turn into your first avoidable outage.
03 / Weeks 9–12
One improvement, then one plan
Month three is where you can start spending the credibility you built in the first two months. I’d keep it simple: make one useful improvement, then write the plan. The improvement gives people something tangible to see, and the plan is much stronger because it comes from what you’ve actually learned.
The one improvement
Small · visible · easy to undo
- Fix something an operator actually complains about, rather than something that simply looks untidy to an architect
- Keep it to one flow, ideally one you’ve identified as relatively low consequence
- Make sure you can undo it quickly if needed
- Good candidates include an alert that reaches the right person, a resubmission that no longer needs a developer, or a report someone has been putting together by hand
The one plan
Written · sequenced · dated only when you can support it
- What the estate actually looks like, based on the traffic map, including what looks ready to retire
- What the main risks are, with someone responsible for each one
- What the platform decision depends on, rather than rushing to name the platform
- What you still need to know before you can give a realistic date
04 / The traps
Three things I’d avoid, even when they’re tempting
All three are tempting for the same reason: they make it look like you’re taking charge. When you’re new to an estate, though, taking your time can be the more responsible move.
Rewrite something early to prove you can fix it
That ugly flow may be ugly because it reflects years of real-world exceptions. Rewriting it in month one, before you understand those exceptions, can turn a working system into an incident with your name on it. You’ll have plenty of time to clean things up once you know why they look the way they do.
Pick the destination platform before you know the estate
The cost and fit of any platform depend on the shape of your estate: endpoint count, message volume, peak-to-average ratio, and how much needs to stay inside your own tenant. You probably won’t have reliable numbers for those in month one. Choose after you have the facts, not because a platform happens to look good in a presentation.
Give a migration date just to make someone feel better
A date that sounds casual in month two can become the date everyone measures you against later. Instead, give people something you can stand behind: what needs to be known before a date can be set, and how long it will take to get those answers.
05 / Day ninety
The test
You’ve got a solid first ninety days behind you
06 / Next
If you’d like a second pair of eyes on the inventory
You can absolutely build the traffic map and consequence map yourself, and if you have the time, I’d recommend doing it. You learn a lot by gathering the information firsthand. An outside review can be useful for the things that come from having seen a lot of estates: recognizing familiar patterns, spotting risks you may not have thought to check, and understanding what different migration options can really involve.
We’ve spent twenty years running BizTalk and enterprise integration in production, and we’re Microsoft V-TSP recognized for BizTalk Server. If you want help, we can do the inventory as an assessment and give you the results. What you do with them afterward is up to you.
Just inherited an integration estate? Sometimes an hour with someone who has been through this before is enough to spot a few things you might otherwise spend months discovering. It doesn’t have to be a sales conversation. Call (678) 203-0800.
Frequently asked questions
What should a new enterprise integration architect do first?
Build two maps and change nothing. The traffic map lists every flow with its message count for the last ninety days, sorted descending, so you know what actually carries traffic rather than what exists in the console. The consequence map records who notices if each live flow stops, how quickly, and what they do — which is built by asking business owners, not by reading the platform. Together they turn a list of artifacts into a plan ordered by risk.
How do I inventory an integration estate I have just inherited?
Start from observed traffic rather than the administration console. An artifact list tells you the size of the estate; a ninety-day message count tells you the shape of it, and in most inherited estates a large share of the artifacts have not moved a message in years. Those become a single retirement list rather than individual work items.
Should I choose a destination platform in my first 90 days?
No. Every integration platform’s economics depend on the shape of the estate — endpoint count, message volume, peak-to-average ratio and how much data has to remain inside your own tenant — and you will not have those numbers in month one. A platform selected before the inventory exists has been selected on marketing rather than on your estate.
Who should a new integration architect talk to first?
The people who get called when integration breaks — usually an operations lead, someone in finance who watches a file arrive, and a partner-facing account manager. They are rarely technical and they know more about the real behaviour of the estate than any document you will find. That conversation is also what produces the consequence map.
What is the biggest risk when taking over an ESB?
A single point of knowledge. One person who understands the orchestrations, or one departed contractor who set up the partner configuration. It is the risk that turns every other incident into a crisis, and the mitigation is entirely within your control: structured interviews, one flow at a time, written down, starting in your first month.
What should I avoid doing in my first 90 days?
Three things, all tempting because they look decisive: rewriting something early to demonstrate competence, choosing a destination platform before the inventory exists, and offering a migration date to make a stakeholder comfortable. The ugly flow is often ugly because reality is ugly; the platform choice depends on numbers you do not yet have; and a date offered casually in month two is the date you are measured against in year two.
How do I know the first 90 days went well?
You can answer six questions without looking anything up: how many flows carry traffic and how many do not, which five would prompt a call within the hour, whose departure would hurt most, when the platform and its dependencies leave support, what actually happens when a malformed message arrives overnight, and what you would need to know before committing to a migration date. None of those is a technology decision.
Jorge Pastorini · Cerebrum City
Cerebrum City is a Microsoft V‑TSP–recognized BizTalk specialist in Atlanta, Georgia, with two decades running BizTalk Server in enterprise production for clients including Humana, Deloitte, JetBlue, and U‑Haul.
Want this mapped against your BizTalk estate?
We inventory your ports, orchestrations, maps, and adapters, flag the interfaces most likely to break, and hand back a staged Azure roadmap. No obligation.